

Software Project Rescue: A Senior Lead's Step-by-Step Playbook
What is software project rescue? (short answer)
Software project rescue is the process of taking over a stalled, unstable, or failing software build, diagnosing why it is failing, stabilizing what users depend on, and deciding whether to refactor, partially rebuild, or rewrite. The goal is to get back to a codebase that can be changed safely.
It is for founders with an abandoned freelancer or agency build, an MVP that stopped scaling, or an AI-generated prototype that breaks once real users arrive. The playbook below follows the order a senior technical lead would use: triage, secure access, audit, stabilize, then decide. You can run the first step yourself before hiring anyone.
Signs your project needs rescue, not just more developers
Here is the core insight: once a codebase is risky to change, adding developers or features makes it worse. More people making more changes to a system nobody fully understands produces more breakage, not more progress.
Every fix breaks something else
Regressions are the clearest signal. When fixing the login page breaks invoicing, the code is tangled and there are no automated tests to catch side effects. That is technical debt charging interest on every change.
Deadlines keep moving and nobody can say why
Slipping dates are normal once. Slipping dates with no clear explanation usually mean there is no visible backlog, no single owner, and scope that changes weekly without anyone writing it down.
Nobody fully understands how the system works
If the person who built a key piece has left and nobody else can explain it, you have knowledge loss. Turnover on a project with no documentation turns every change into archaeology.
The demo works but real users break it
The app looks fine on the founder's laptop, then falls over with fifty concurrent users, odd inputs, slow networks, or real payment edge cases. This is especially common with rushed and AI-generated builds.
Your developer or agency has gone quiet or left
Slow replies, vague status updates, or a sudden exit leave you holding a product you cannot change. This is the most urgent case, because access to your own systems may be at risk.
Quick self-check. Answer yes or no:
Have the last few releases each introduced new bugs?
Has the launch or delivery date moved more than twice?
Would losing one specific developer leave you unable to ship?
Do you lack admin access to your code repository or hosting?
Are there no automated tests you know of?
Do users report problems you cannot reproduce?
Two or more yeses means it is time to stop adding features and assess. For a fuller self-assessment, use our free 30-point software project rescue checklist.
Step 1: Triage and secure access in the first 48 hours
Most guides skip this step, and it is the one that hurts most when ignored. Before anyone reviews a line of code, make sure you, the business, own and control every system the product depends on.
Get control of repos, hosting, domains, and third-party accounts
When a vendor relationship ends badly, whoever holds the accounts holds the product. You want each of these registered to a company email you control, with you as owner or admin, not just a guest:
Asset | What to confirm |
|---|---|
Git repository (GitHub, GitLab, Bitbucket) | Your organization owns it, you have owner rights |
Cloud and hosting (AWS, Vercel, Supabase, etc.) | Billing and root/admin access are yours |
Domain registrar | Domain is in your account, auto-renew is on |
DNS provider | You can log in and edit records |
App Store and Google Play | Developer accounts are under your company |
Stripe or payment provider | You are the account owner |
Email provider (transactional and workspace) | Admin access and sending domain control |
API keys (OpenAI, maps, SMS, CRM) | Keys live in accounts you own |
Analytics and error tracking | You have admin logins |
If a former vendor holds any of these, request a transfer in writing now, while the relationship is still civil. Then change passwords and remove access you do not recognize.
Freeze non-critical feature work
Stop new features until you understand what you have. Only fixes for revenue-blocking or user-blocking bugs should ship. This feels slow, but every new change to an unknown system adds risk.
Back up the production database and code
Take a full database backup and store it somewhere you control, separate from the current host. Clone the repository locally. If anything goes wrong during handover, you can recover.
List the business-critical flows that must not break
Write down, in plain language, the five to ten things that make or protect money: sign up, log in, checkout, billing renewal, the core workflow customers pay for, admin reporting. This list drives every later decision.
What you should have at the end of Step 1: full ownership of every account, a verified backup, a feature freeze, and a written list of critical flows.
Step 2: The code and delivery audit
An audit answers one question: what state is this product really in, and what does it cost the business? A focused audit typically takes a few days to a couple of weeks, depending on the size of the codebase and how much documentation exists.
Can it be built and deployed from scratch?
The first test is simple: can a new developer clone the repo, set it up, and deploy it using only what is in the repo and your accounts? If the answer is no, the project depends on one person's laptop, and that is the first thing to fix.
Architecture and data model review
The auditor checks whether the structure of the system and the database matches how your business actually works. A messy screen is cheap to fix. A data model that cannot represent your customers, plans, or orders correctly is expensive, because everything sits on top of it.
Security and secrets exposure
This covers passwords and API keys committed to the code, missing permission checks, outdated libraries with known vulnerabilities, and how user data is stored. Exposed secrets are treated as urgent.
Tests, CI/CD, and release process
Are there automated tests? Does code go through an automatic build and check (CI/CD) before release, or does someone copy files to a server? A fragile release process is one of the most common reasons fixes keep breaking things.
Integrations (payments, CRM, ERP, AI APIs)
Failing integrations quietly cost money: Stripe webhooks that miss renewals, HubSpot or NetSuite syncs that duplicate records, Shopify orders that never arrive, OpenAI calls with no limits or error handling. The audit checks each connection for retries, logging, and failure handling. This is the core of our API and third-party integration work.
What you should receive at the end
Insist on written deliverables you can understand without a translator:
A risk map ranked by business impact, not by how interesting the problem is to engineers
A list of quick wins that reduce risk within days
An architecture summary in plain language, with a simple diagram
A recommendation: refactor, partial rebuild, or rewrite, with reasoning
Documentation of setup and deployment, so knowledge no longer lives in one head
If you get a vague slide deck and a quote, you did not get an audit.
Step 3: Stabilize before you build anything new
Stabilization means making the current product safe to operate and safe to change. Order matters: protect revenue and user-critical paths first.
Add monitoring and error tracking
You cannot fix what you cannot see. Error tracking and uptime monitoring tell you about failures before customers email you, and they give real data on what breaks most often.
Put tests around the critical flows first
Do not aim for full test coverage. Write automated tests for the flows from your Step 1 list: signup, checkout, billing, the core workflow. These tests act as a safety net so later changes cannot silently break what pays the bills.
Fix the release process so deploys are boring
Set up CI/CD so every change is built, tested, and deployed the same way, with a staging environment and an easy rollback. A good deploy is uneventful.
Patch security holes and rotate leaked keys
Any key that was ever exposed, in code, chat, or a former vendor's hands, gets rotated. Close the permission gaps the audit found.
Re-establish a simple project management rhythm
Founders often ask which project management tool to use. Jira, Linear, Trello, Asana, and ClickUp are all fine. The problem is rarely the tool. It is the lack of a single owner and a visible backlog. Pick one tool, keep one prioritized list, and hold a short weekly review where someone accountable reports what shipped and what is blocked.
Step 4: Rewrite vs. refactor: how to actually decide
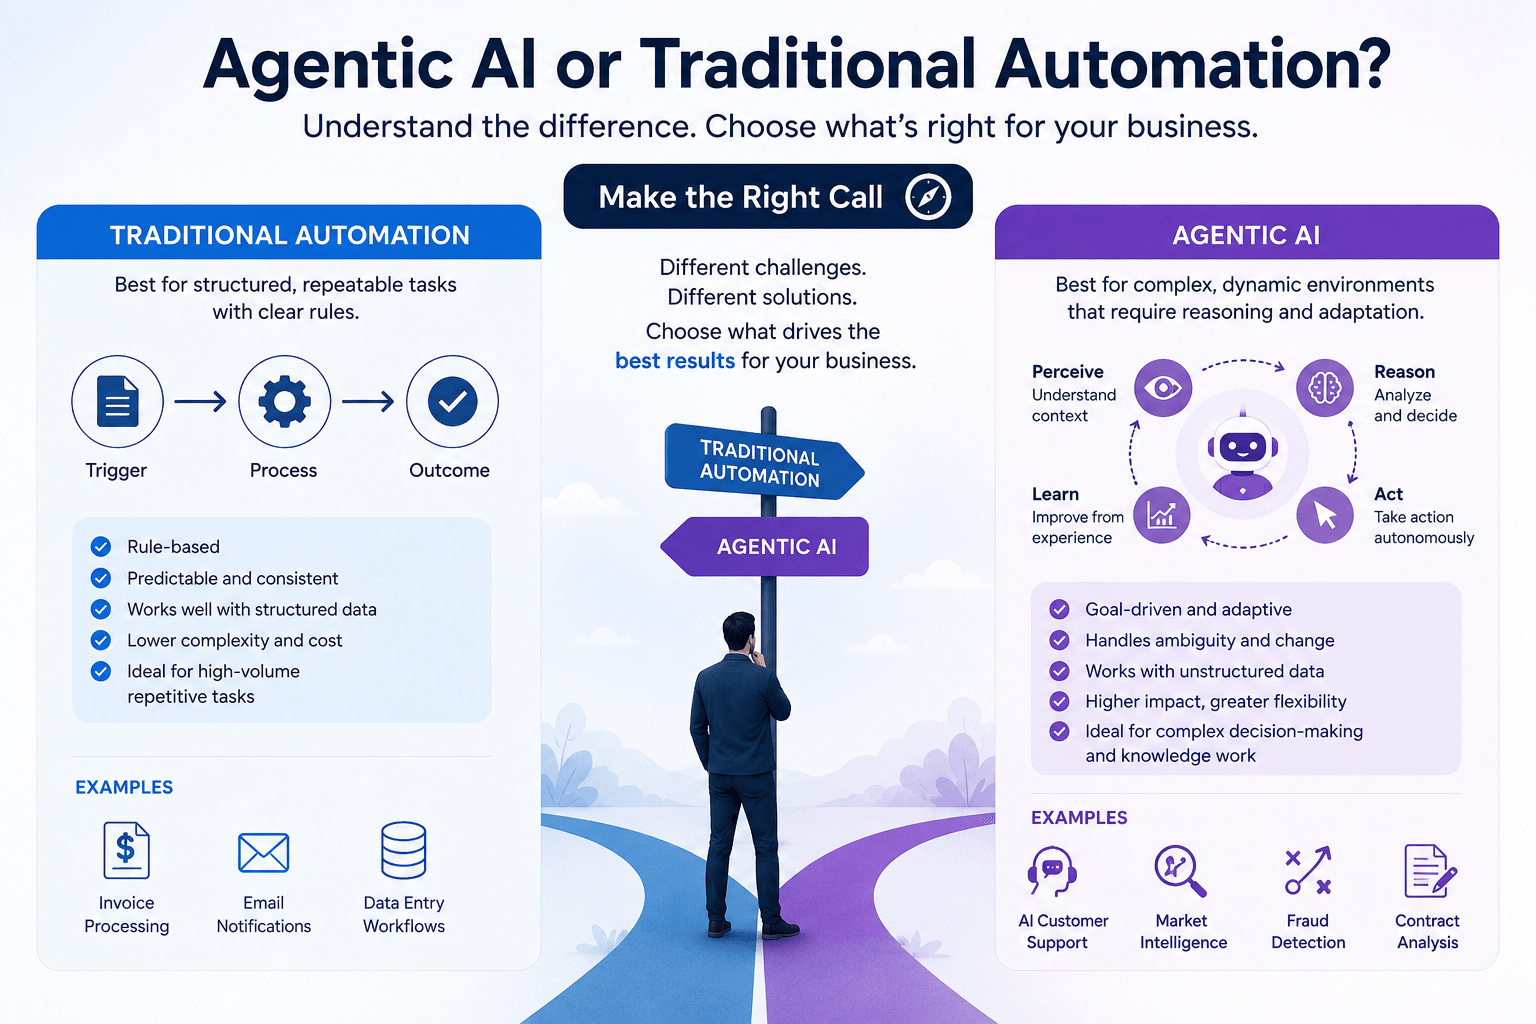
This is the decision that defines the rescue. Rewrites are tempting because a clean slate feels faster. They are also routinely underestimated, because the old system contains years of undocumented rules and edge cases that must be rediscovered. When real users exist, incremental replacement is usually safer.
Situation | Refactor | Partial rebuild | Rewrite |
|---|---|---|---|
Data model fits the business | Yes | Mostly | No |
Stack still supported and easy to hire for | Yes | Yes, or migrating | Obsolete or unhireable |
Paying users depend on it | Strongly favored | Favored | Risky, needs a migration plan |
Security problems | Fixable in place | Concentrated in some areas | Pervasive |
Undocumented business logic | Lots (keep it running) | Moderate | Little, or easy to re-specify |
Runway left | Short | Medium | Long enough to run two systems |
When refactoring wins
If the data model is sound, the stack is current, and the problems are messy code and missing tests, refactor. Improve the code piece by piece behind the tests you wrote in Step 3. Users never notice, and you keep shipping.
When a partial rebuild (strangler approach) makes sense
The strangler approach replaces the worst parts of a system one at a time while the rest keeps running. You might rebuild billing or a slow reporting module on a new foundation, route traffic to it, then retire the old piece. It limits risk and shows progress early. We cover the techniques in detail in our guide on how to scale your web app without a full rewrite.
When a full rewrite is justified
A rewrite makes sense when the data model is fundamentally wrong, the stack is unsupported, security problems are everywhere, and either there are few users or there is enough runway to build the new system while the old one keeps running. Small, early products with little real usage are the best rewrite candidates.
Questions to ask before approving a rewrite
What exactly will the new version do that the current one cannot, and why can that not be fixed in place?
Who has written down all the business rules the current system enforces?
How will existing data and users be migrated, and what is the rollback plan?
Who maintains the old system during the rewrite?
What gets delivered in the first few weeks that proves the plan works?
When a project is not worth saving
Sometimes the honest answer is to stop. If the product has no users, the market assumption behind it has changed, and the code would need a full rewrite, it may be better to keep the designs and lessons and start a smaller, cleaner version, or pause entirely. A good rescue partner will say so.
Rescuing AI-generated and vibe-coded apps
AI coding tools can produce an impressive working demo in days. The trouble starts when real users, real data, and real money arrive. If you are new to the term, here is what vibe coding is and where it breaks down.
Common failure patterns we look for
No server-side authorization. The interface hides buttons, but the backend accepts any request, so one user can read or edit another user's data.
Secrets in client code. API keys for OpenAI, Stripe, or the database shipped to the browser where anyone can copy them.
Supabase row-level security left off. Tables readable or writable by anyone with the public key.
Duplicated logic. The same rule written five slightly different ways, so fixing one copy leaves four bugs.
Inconsistent data models. Fields that mean different things in different places, and no constraints to stop bad data.
Missing error handling. A failed payment or a slow API call leaves the app in a broken state with no message and no log.
No tests. Nothing catches regressions when the AI tool regenerates code.
What can usually be kept
The UI and the product thinking are often worth keeping. The screens, flows, and decisions about what the product does represent real validation work. In many cases the frontend stays, while the backend gets proper authentication, authorization, data constraints, and tests underneath it.
Why software projects fail (and how to avoid a second failure)
A rescue that does not address why the first attempt failed tends to fail again.
Real-world examples of failed software projects
Large, well-documented failures show the same patterns at bigger scale:
HealthCare.gov (2013): the launch buckled under real traffic. Public reviews pointed to fragmented ownership across many contractors and too little end-to-end testing before go-live.
FBI Virtual Case File: a case management system abandoned after years of work, widely attributed to shifting requirements and weak technical oversight.
Knight Capital (2012): a deployment left old code active on one server, and automated trading went wrong within minutes. A release process problem, not a coding genius problem.
The 40/20/40 rule and what it says about rushed builds
The 40/20/40 rule is a rule of thumb for effort on a software project: roughly 40% on planning and design, 20% on writing code, and 40% on testing and integration. It is not a law, but it captures a truth: code is the smaller part of shipping software that works.
Rushed and vibe-coded builds often invert this, spending almost everything on code and very little on design or testing. That is exactly why they look finished in a demo and fail in production.
The root causes we see repeatedly:
No single technical owner, so decisions and accountability are scattered
Unclear requirements and scope that changes without being written down
Inexperienced teams without senior review
Accumulated technical debt with no tests to contain it
Communication gaps between business and developers
Unrealistic expectations about timelines and budgets
Vendor handoffs where knowledge is lost each time the project changes hands
How to choose a software project rescue company
Questions to ask before you hire
Will you audit before quoting a rewrite?
Who is the actual senior person doing the work, and will I talk to them directly?
Will I own all code, accounts, and documentation from day one?
What will I have in hand at the end of week one?
Will you tell me if the project is not worth saving?
How will knowledge be documented so I am never locked in again?
Red flags
An immediate rewrite pitch before anyone has seen the code
A senior salesperson up front and junior-only developers behind them
Vague deliverables like "assessment phase" with no written outputs
Refusal to work in your repository and your accounts
No mention of tests, monitoring, or release process
What a good engagement looks like
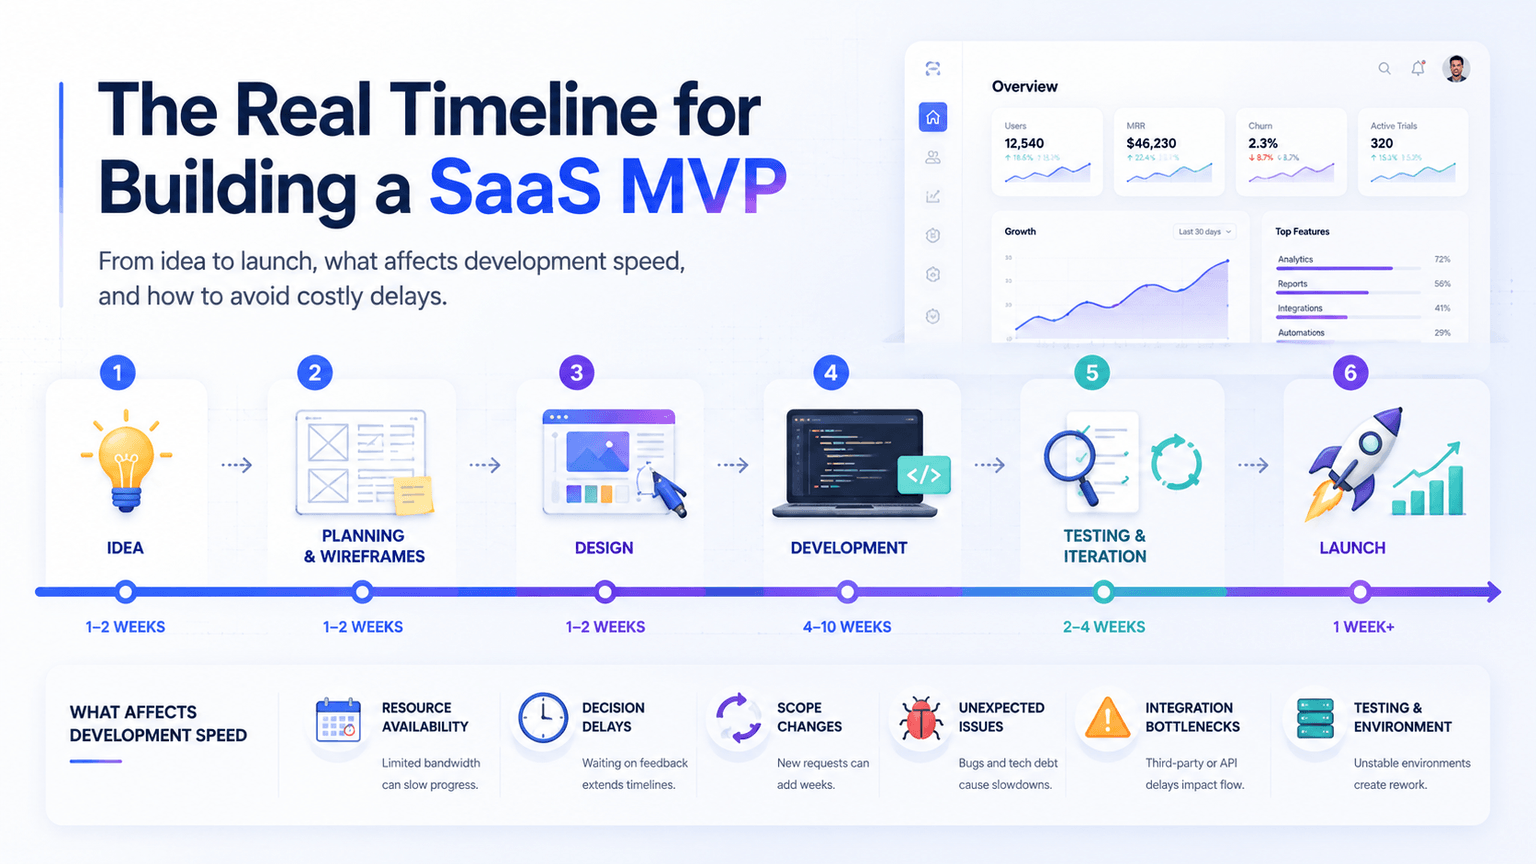
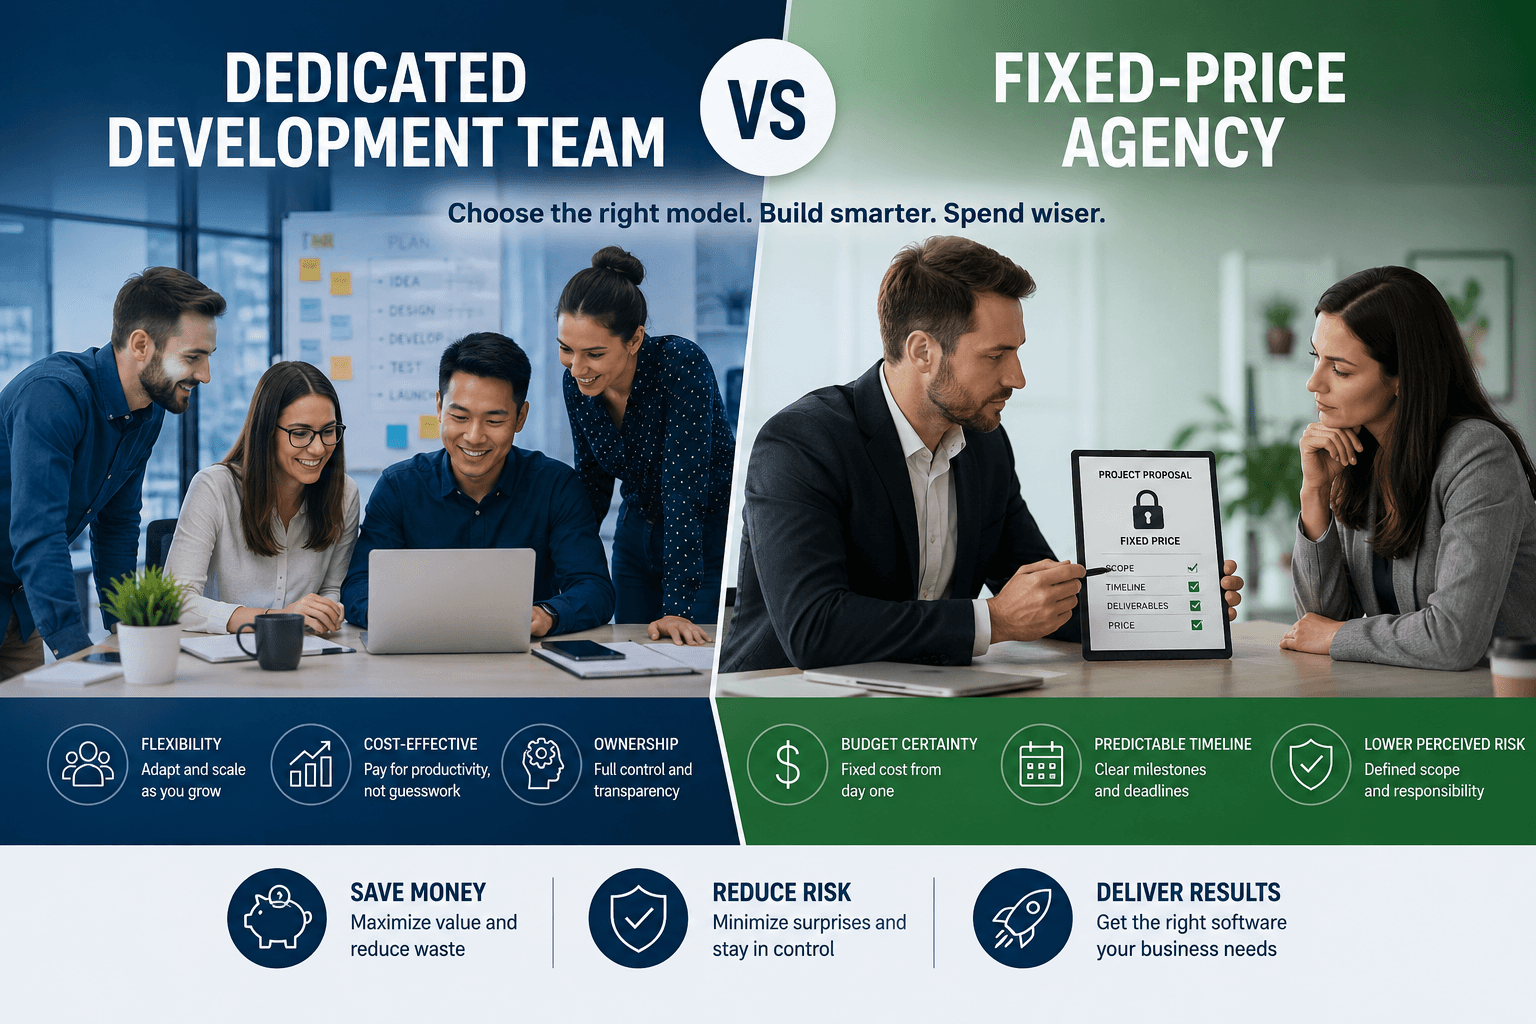
A good rescue starts with access and an audit, delivers written findings, stabilizes critical flows, then makes the refactor or rebuild decision with you. How long it takes depends on the size and state of the system: stabilization is often measured in weeks, while a partial rebuild can run longer. The engagement model matters too, and our comparison of a dedicated team vs. fixed-price agency explains why open-ended rescues rarely fit a fixed price.
It should end with a proper handover: documentation, a working deployment pipeline, monitoring in place, and a plan for ongoing maintenance, whether that is your own team or continued support.
At NextGen Software, one senior technical lead owns each rescue from audit through relaunch. That is deliberate. Most failing projects we see failed at handoffs, between freelancers, agencies, and internal developers, where knowledge and accountability leaked out. A single owner who works in your repo and accounts, in stacks like Vue/Nuxt, React, Node, Supabase, AWS, and Vercel, removes that failure point.
Next step: get a clear read on your project
Start with the self-assessment: the free 30-point software project rescue checklist walks you through access, code health, and delivery risks in an hour or two, no developer needed.
If the checklist confirms what you suspected, book a free discovery call and talk to a senior technical lead about your project. You will get an honest read on whether it can be saved, what to secure first, and what a sensible next step looks like, even if that step does not involve us.
Frequently Asked Questions
Can a new team take over a project from another developer or agency?
Yes, and it is common. The handover goes much better if you first secure ownership of the repository, hosting, domains, payment accounts, and API keys. The new team should then audit the code and document setup and deployment before changing anything significant.
How long does a software project rescue take?
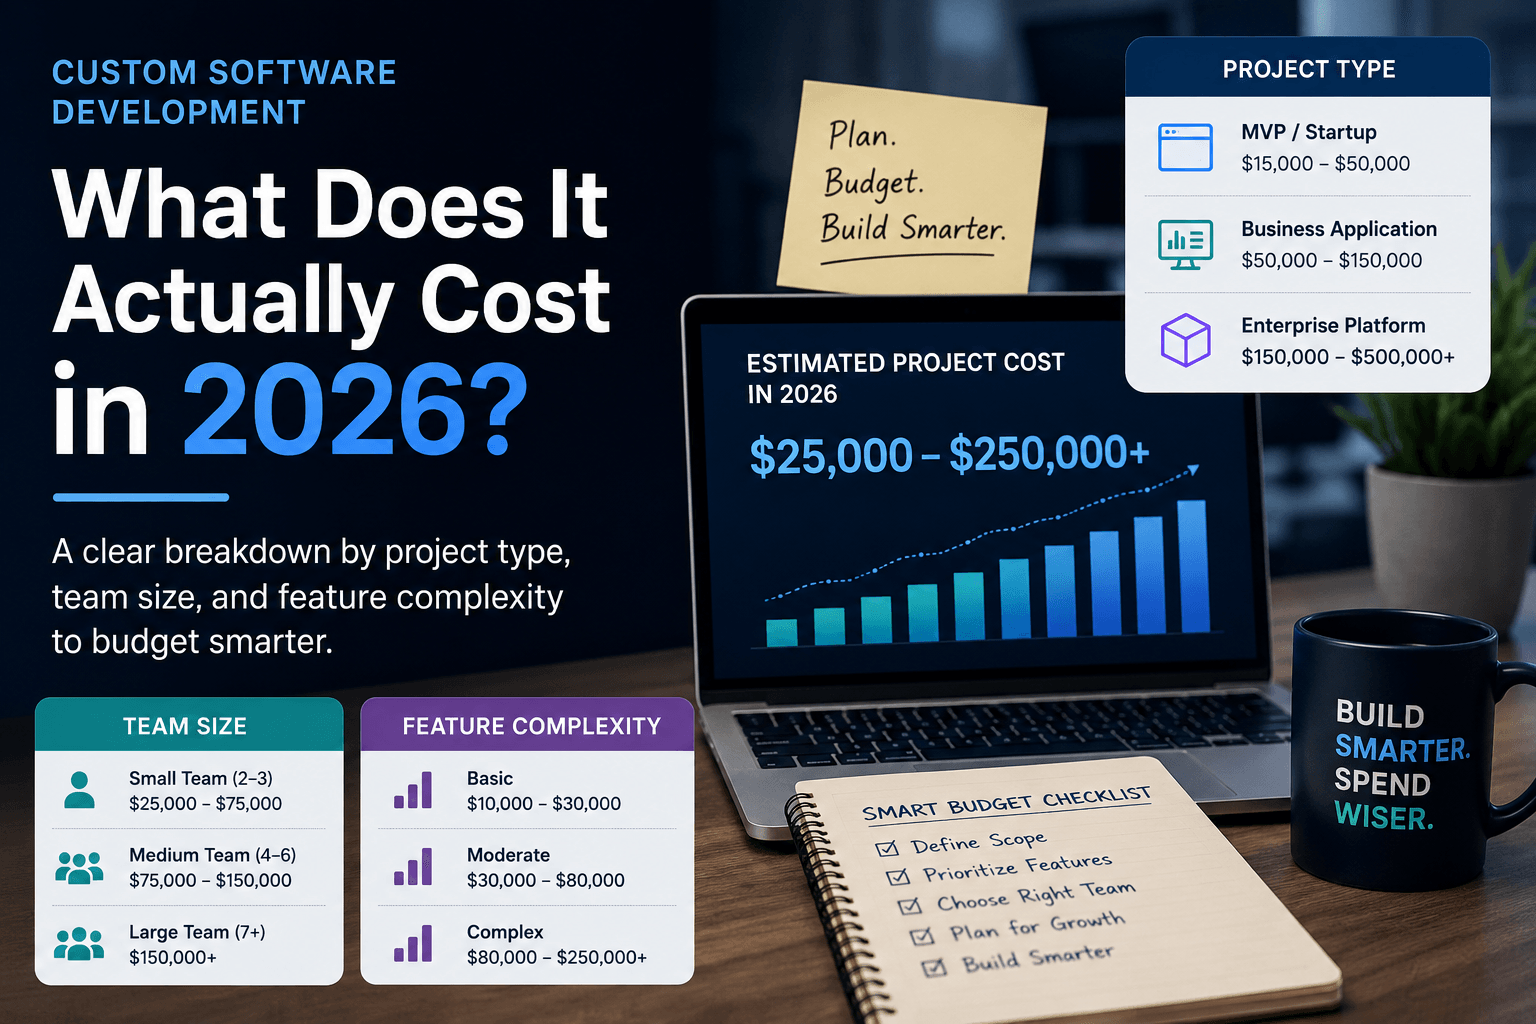
It depends on the size and condition of the system. A focused audit typically takes a few days to a couple of weeks, and stabilizing critical flows is often measured in weeks. Partial rebuilds or rewrites take longer and should be planned in stages with visible progress.
Should I rewrite or refactor my existing codebase?
If the data model fits your business, the stack is current, and you have paying users, refactoring or a partial rebuild is usually safer. A full rewrite makes sense when the foundation is fundamentally wrong and you have the runway to run old and new systems side by side. Always audit before deciding.
Can you fix AI-generated or vibe-coded apps that fail in production?
Usually, yes. The typical problems are missing server-side authorization, exposed secrets, Supabase row-level security turned off, duplicated logic, and no tests. The UI and product decisions are often worth keeping while the backend is hardened underneath.
When is a software project not worth saving?
When there are no real users, the business case has changed, and the code would need a full rewrite anyway. In that case it is often better to keep the designs and lessons and start a smaller, cleaner build. A trustworthy rescue partner will tell you this directly.